Data Lake and ETL diagram template
Land raw data in object storage, transform on a schedule and load a warehouse.
About this design
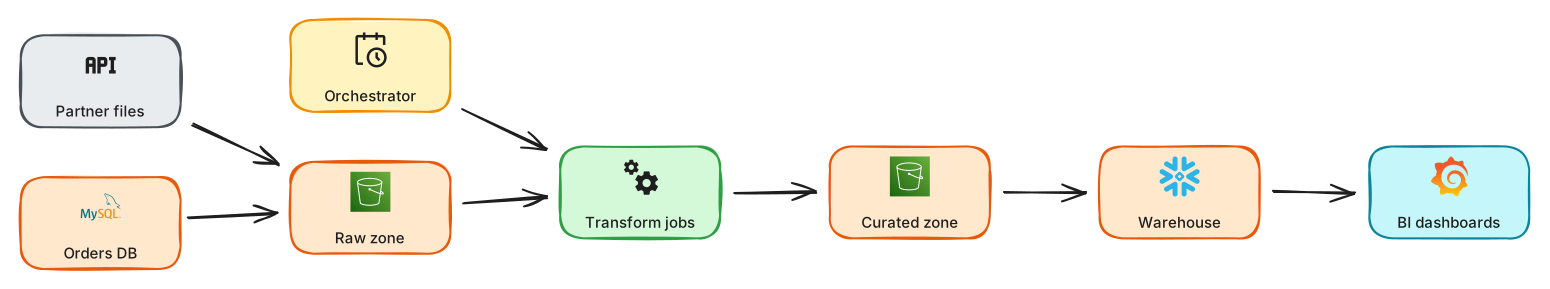
A data lake keeps raw data in cheap object storage so that nothing is lost and questions you have not thought of yet can still be answered later. Sources such as application databases and partner files are extracted on a schedule and written, untouched, into a raw zone. Transform jobs on a distributed engine clean, join and conform that data into a curated zone, and the results are loaded into a warehouse that analysts query with SQL. A scheduler orchestrates the dependencies so that a late input delays only what depends on it. Use this template to discuss batch versus streaming, schema evolution when a source adds a column, partitioning files by date to keep scans cheap, data quality checks between zones, and who is allowed to see personal data once it has been copied three times.
Diagram as text
This is the source of the diagram, in the ArchBoard diagram DSL. Paste it into Tools, Diagram from text to rebuild or change it.
title "Data lake and ETL"
direction LR
db mysql "Orders DB" -> storage s3 "Raw zone"
external "Partner files" -> raw-zone
raw-zone -> worker spark "Transform jobs" -> storage s3 "Curated zone" -> warehouse snowflake "Warehouse"
scheduler "Orchestrator" -> spark
warehouse -> monitor grafana "BI dashboards"